We trained Orion-16B without a reserved cluster anywhere in it.
 Macrocosmos@MacrocosmosAI
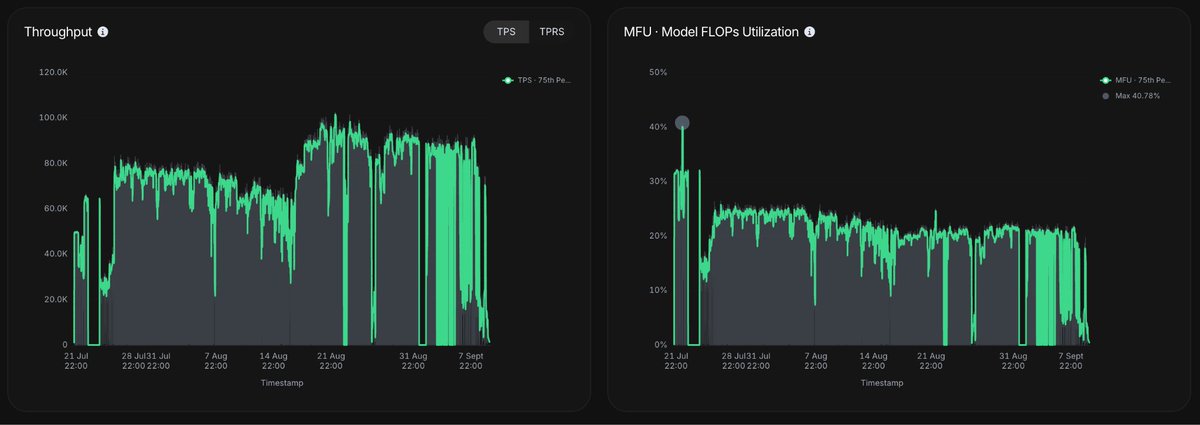
We trained Orion-16B without a reserved cluster anywhere in it. The numbers underneath that: It sustained around 80k tokens per second across 4090s, 5090s, A100s, L40s, and A6000s, at roughly 20% MFU. The accessible pool came to about 18 B200s equivalent at FP16. Nodes dropped, throughput swung, and machines ran inconsistently throughout. Training carried on without direct intervention. Imperfect compute, one finished model.
More from the feed
PressNetwork-wideIntelligence — tao.media · just now
What Is Tempo on Bittensor? How Epochs Settle Subnet RewardsTaosis indexes announcements, articles, posts and releases about Bittensor subnets from their own channels and keeps a record of each. The text above is the source’s; the figures are read from the chain by Taosis.